
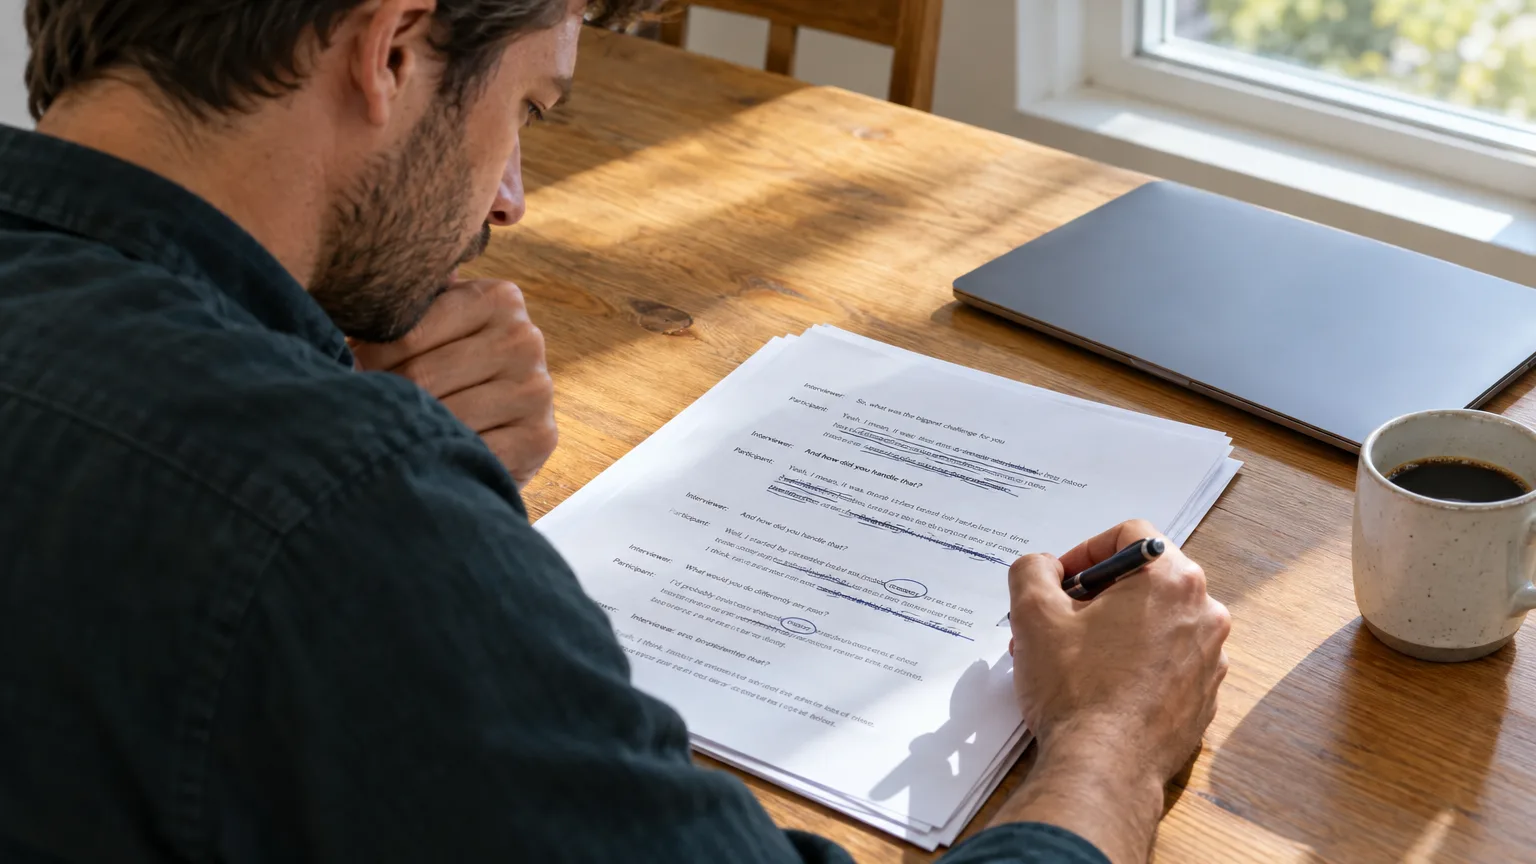
How to Edit a Talking-Head Video: Read the Transcript Before You Touch the Timeline
Somewhere a solo creator is on the third rewatch of a 35 minute recording, looking for the two sentences that will actually make the lesson, pausing every few seconds to write down a timestamp by hand. We've all sat through that afternoon. A talking-head video edits fastest when you work the words before the picture: read the transcript, mark the selects, strip filler at the word level, then solve the jump cuts that creates with a zoom, a cutaway, or a second angle. Most editors do it backwards. They open the timeline, scrub to find the good parts, trim by ear, and only think about jump cuts once the footage already looks chopped. That order works. It is just slow, and it is the reason a 40 minute recording can eat an entire afternoon. Here is the faster order, with a worked example and the mistakes that undo it.
Read first
Why start with the transcript instead of the timeline?
Scrubbing a 40 minute talking-head recording to find the good sections is slow because video only plays back in real time, and a transcript does not have that limit. Your eyes move faster than the speaker talks, so you can read the whole recording, mark what to keep, and move on in a fraction of the runtime. If your tool ties word-level timecode to that text, each mark is already a precise in and out point on the clip, not a rough guess you will fine-tune later on the timeline.
This is the same logic behind a paper edit, the practice of building the structure of a non-fiction cut on the page before touching a timeline. Documentary editors worked this way long before AI transcription existed, cutting paper transcripts with scissors and tape. A talking-head video is a simpler version of the same problem: one speaker instead of a room full of them, but the same win from reading instead of scrubbing.
Creator Ali Abdaal is a useful reference here, not because the method is novel to him, but because the scale makes the savings obvious: a channel with 6.71 million subscribers and over 570 million total views is built almost entirely on talking-head videos, and the public editing advice coming out of that channel treats the first pass as ruthless filler and tangent removal before any visual polish goes on top. That is the order this guide is arguing for, just applied at a scale where the time savings compound across hundreds of uploads.
The payoff scales with length. A five minute clip forgives a scrub-and-guess approach. A 45 minute course lesson or webinar recording does not: watching it once at playback speed to find the good sections already costs you 45 minutes, before a single cut is made. Reading covers the same ground in a fraction of the time, which is why transcript-first workflows scale to long recordings in a way frame-by-frame scrubbing never does. ScriptCut ties word-level timecode to the transcript for exactly this reason. AI Select marks the strongest moments automatically while you read, so every mark is already a cut point, and you can build more than one version of the edit from the same master transcript without losing the original.
Remove fillers
How do you cut dead air and filler words without hours of waveform hunting?
Do this pass on the transcript before the visual timeline opens at all. "Um," "you know," repeated words, and false starts add up to real minutes once you count them across a 20 minute recording, and removing them at the text level means deleting words, not scrubbing a waveform for silence.
This pass is usually the biggest single time investment, since it touches nearly every sentence. Two rules keep it from sounding chopped:
- Do not remove every pause. A short beat before an important sentence is a rhetorical tool, not dead air.
- Leave enough breath and mouth movement around each cut point so the audio does not click or pop when two words that were never adjacent collide.
A tool built around a transcript-based workflow can run this pass with a single command rather than a manual scrub, which is exactly where a transcript-based editor earns its keep over a traditional timeline tool. ScriptCut's Cleanup step does this automatically, marking filler words for removal across the whole transcript in one go.
Tighten the rambles
What about whole tangents, not just individual words?
Filler removal handles the small stuff. The bigger win is cutting entire rambling passages: the ones where a speaker circles back to a point already made, or wanders onto something that never pays off. Read the transcript the way you would read a script for a scene that is not earning its runtime, and cut the whole passage, not just the filler words inside it. This is also where the paper-edit idea of working "inside-out" matters. You are not imposing a script on the footage. You are finding the strongest version of what the speaker actually said and building around that.
Hide the jumps
How do you fix the jump cuts that removing words creates?
Removing words from a single continuous shot creates jump cuts: the speaker's head or hands visibly snap between positions. There are three standard fixes, and most finished talking-head videos use more than one.
- Zoom punches. A small push in or out on the cut hides the jump because the frame itself changes, not just the subject.
- B-roll covers. Cutting to a screen recording, a product shot, or B-roll over the audio cut removes the visual jump entirely and adds information at the same time.
- Embrace the jump cut as style. Fast, visible jump cuts have become their own recognizable pace for short-form and tutorial content, as long as they stay consistent rather than random.
If you shot with a second camera or a wide safety angle, this is where it earns its keep: cutting to the second angle on every trim avoids the jump entirely without a single piece of B-roll. The tutorial below walks through the in-camera and in-edit versions of all three fixes.
Set up for it
What should you do before you even hit record?
The fastest talking-head edits are partly won before you hit record. Capture a few seconds of room tone at the start of every session, silence with nothing said, so you have clean audio to fill any gap a cut leaves behind. If a take goes wrong, pause and restart the sentence cleanly rather than talking over the mistake. A clean restart is far easier to cut around than a stumble buried mid-sentence. If a second camera or a wide static angle is available, run it for the whole session even if you doubt you will need it. It costs nothing during the shoot and gives you a free jump-cut cover for every trim in the edit.
On the back end, generate captions after the cut is locked, not before. Doing it earlier means redoing captions every time a line moves during editing. This matters on platforms where most watch time happens with sound off: clean, accurate captions and expressive on-screen text keep viewers who would otherwise scroll past in the first two seconds. If you ever need to move caption files between formats or clean up a DaVinci Resolve caption export, this free SRT to VTT converter handles that without a signup.
Worked example
How does a 35 minute recording become an 11 minute lesson?
Take a 35 minute solo recording for a course lesson. Reading the transcript at reading speed takes roughly 12 to 15 minutes, well under the 35 minutes it takes to scrub the raw footage once, let alone twice. Filler and false-start removal typically shaves 15 to 20 percent off the runtime on its own, before any tangents are cut. Cutting two rambling tangents identified in the read-through takes the piece from about 29 minutes down to 11. The visual pass, adding zoom punches and two B-roll inserts over the roughest jump cuts, is the last step, done against audio that is already locked.
Break that down by stage and the savings compound rather than add up. The read-through replaces what would otherwise be a full scrub of the raw footage, saving roughly 20 minutes on its own. Marking and removing filler at the text level, rather than hunting for each "um" on a waveform, saves another chunk because you never have to relisten to confirm a cut point. The transcript already shows exactly where the word starts and ends. By the time the video timeline opens at all, the hard part, deciding what stays, is finished. What's left is mechanical: trim to the marked points, cover the resulting jump cuts. (The CEO cameo at minute 19, the one about "circling back to synergy," does not survive the read-through. It never does.)
Common mistakes
Where do talking-head edits actually go wrong?
Cutting purely for pace without listening back is the most common mistake. A transcript-level cut can read fine on the page and still sound unnatural once you hear the actual audio, so always do a listen-through pass after the text edit. The second mistake is trimming every pause to the same tight interval, which flattens the speaker's natural rhythm and makes even honest delivery sound artificial. The third is skipping a second safety angle on camera, which limits your jump-cut options later to zoom punches and B-roll alone.
A fourth, quieter mistake is editing in a tool that separates the text from the footage's actual timecode. If your marks are not tied to word-level timecode, every deletion still has to be manually matched back to a point on the timeline, which erases most of the speed advantage of reading over scrubbing in the first place. A transcript-based editor exists specifically to keep that link intact from the first read-through to the final export, which is the whole point of working this way at all. If you're deciding between tools, a transcript studio workflow in Premiere Pro is one path, and a dedicated transcript-first app that hands off a frame-accurate timeline is another; the right one depends on how much of the pre-edit you want the NLE to own versus a separate tool.
Honest tradeoffs
How tight should the cut actually be?
Aggressive filler removal works well for tutorials, ads, and short-form clips where attention is scarce and the goal is information density. It works less well for long-form conversational content, like a podcast-style interview, where some of the value is in hearing someone think out loud, pauses and all.
The Lex Fridman Podcast is the clearest example of the opposite instinct: multi-hour conversations released close to unedited, a format one Columbia Journalism Review profile called "expansive, compelling, anti-journalistic," precisely because it resists the tight, cut-for-density style that works for a tutorial channel. Neither approach is more correct. Match your cut density to the platform and the format, not to a fixed rule about how many filler words are acceptable. A 90 second product demo earns a hard cut on every pause. A long-form conversation earns the opposite treatment, and cutting down a long interview for highlights is a different job from cutting a talking-head explainer, even though both start from the same transcript-first read.
After it's cut
What happens to the footage once the talking-head edit is locked?
A locked talking-head video is rarely the end of the job anymore. Most teams need a handful of short clips pulled from it for social, and doing that manually means rewatching the finished edit with a stopwatch, which defeats half the point of having cut it efficiently in the first place. This is a separate job from the edit itself, and it is worth treating it that way: ScriptCut Social can take the locked video (or the original long recording) and find the moments worth posting, frame them on the speaker, caption them, write a platform-specific description for each one, and schedule them, with one link for a client to approve before anything goes out.
The takeaway
So what's the actual order?
The fast path through a talking-head edit is text, then picture: read and mark the transcript, cut filler and tangents at the word level, then solve the jump cuts you created with zoom punches, B-roll, or a second angle. Doing it backwards, cutting picture first and hoping the audio holds together, is where most of the wasted time in this format comes from.
The order scales the same whether you are cutting a two minute update or a 90 minute course module. The tools and export formats change depending on where the finished file needs to live, but the sequence stays fixed: read, mark, remove, cover the jumps, listen back. Editors who skip straight to the timeline are not saving a step. They are doing the reading step later, at playback speed, with the added cost of scrubbing back and forth to find what they already passed. Here is how we'd start a new recording: read the transcript first, mark the selects, and only then open ScriptCut to let AI Select and Cleanup do the first pass before anything touches a timeline.
Sources
frequently asked questions
Yes, or at least enough of it to find the usable material. Transcribing first is what lets you read for selects instead of scrubbing, which is the entire time savings this workflow is built on.
Filler words and false starts typically take 15 to 20 percent off on their own, and cutting full rambling tangents on top of that can take a 35 minute recording down to well under a third of its original length, depending on how tight the speaker's delivery was.
Yes, if the style supports it. Fast, visible jump cuts are an accepted pace for short-form and tutorial content as long as they're applied consistently rather than scattered randomly through the edit.
It is not required, since zoom punches and B-roll can cover every jump cut on their own, but a second angle gives you a third option that needs no extra footage to be shot or sourced.
After. Captioning before the cut is locked means redoing the caption timing every time a line moves, which happens often during the filler and tangent removal passes.
The reading-first step still applies, but the cutting density should loosen. Long-form conversational formats often keep more pauses and tangents on purpose, since some of the value is in hearing someone think out loud.
You might also like...














Get the next ScriptCut article in your inbox
One short email a week. Editing tips and product news. No spam, unsubscribe anytime.
Start selecting.

Pick the story in the transcript, export a finished rough cut and ready to post short form video.
What are you looking for?
Get the ScriptCut newsletter
Thanks! Check your inbox to confirm.
Something went wrong. Please try again.